EgoPhys turns a single egocentric RGB interaction into a predictive deformable physical twin, using shared residual physics to improve held-out prediction and enable robot planning and physical execution.
Abstract
Humans naturally understand object physics through everyday interactions, but predicting how deformable objects, such as soft objects and fabrics, respond to manipulation remains a major challenge for computer vision and robotics. Existing deformable physical twin methods typically rely on controlled multi-view or depth capture and costly per-object physical refinement. We present EgoPhys, a framework for constructing predictive deformable physical twins from a single egocentric RGB interaction. EgoPhys combines persistent correspondences with per-frame monocular 3D observations to fit a sequence-specific spring-mass model from moving-camera observations. Because a short interaction weakly constrains fine-grained local stiffness, EgoPhys amortizes this refinement across training interactions using a compact state-conditioned residual model that predicts bounded local corrections around the sequence-specific estimate and remains frozen at test time. Experiments show improved held-out future prediction over adapted deformable-twin baselines, with the amortized residual further improving prediction while reducing local-refinement cost by approximately 10x-59x over dense per-spring optimization. The resulting twins also support deformable-object action selection, with representative physical robot manipulation providing a qualitative proof of concept.
Method
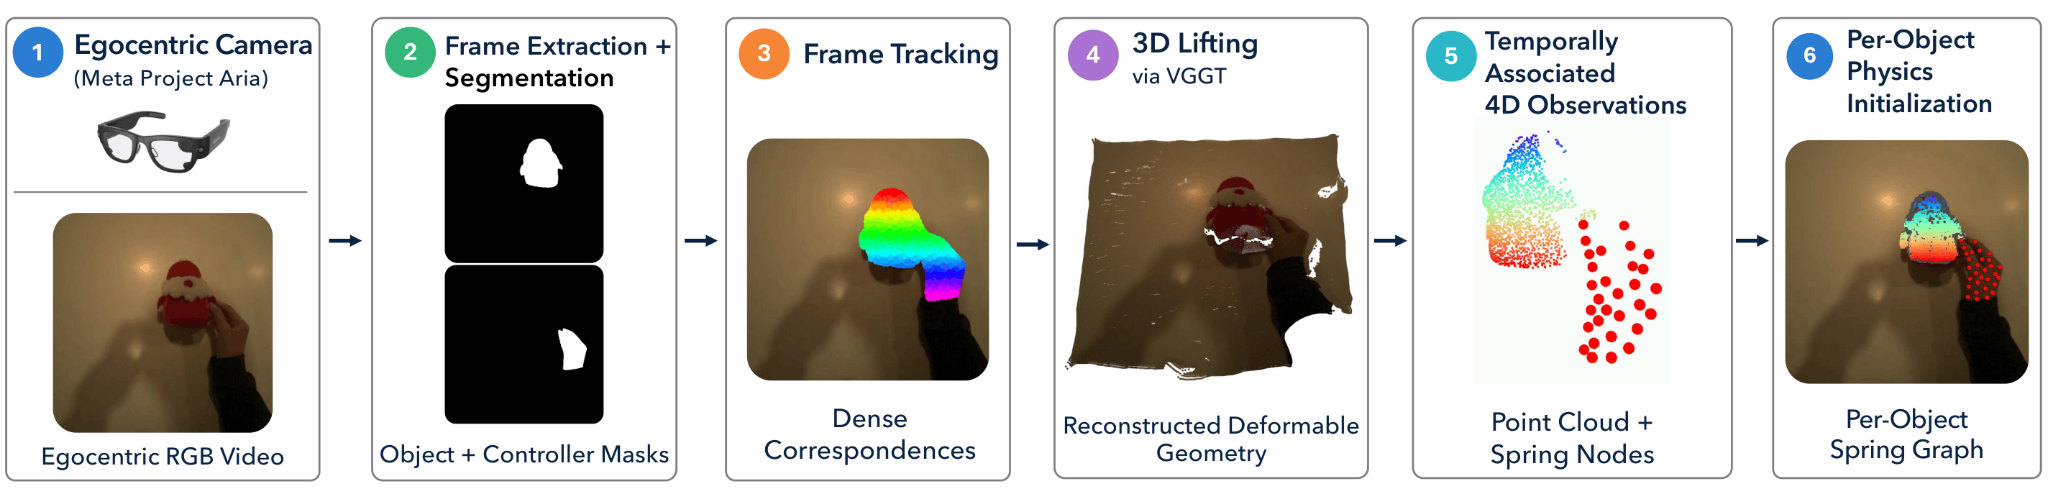
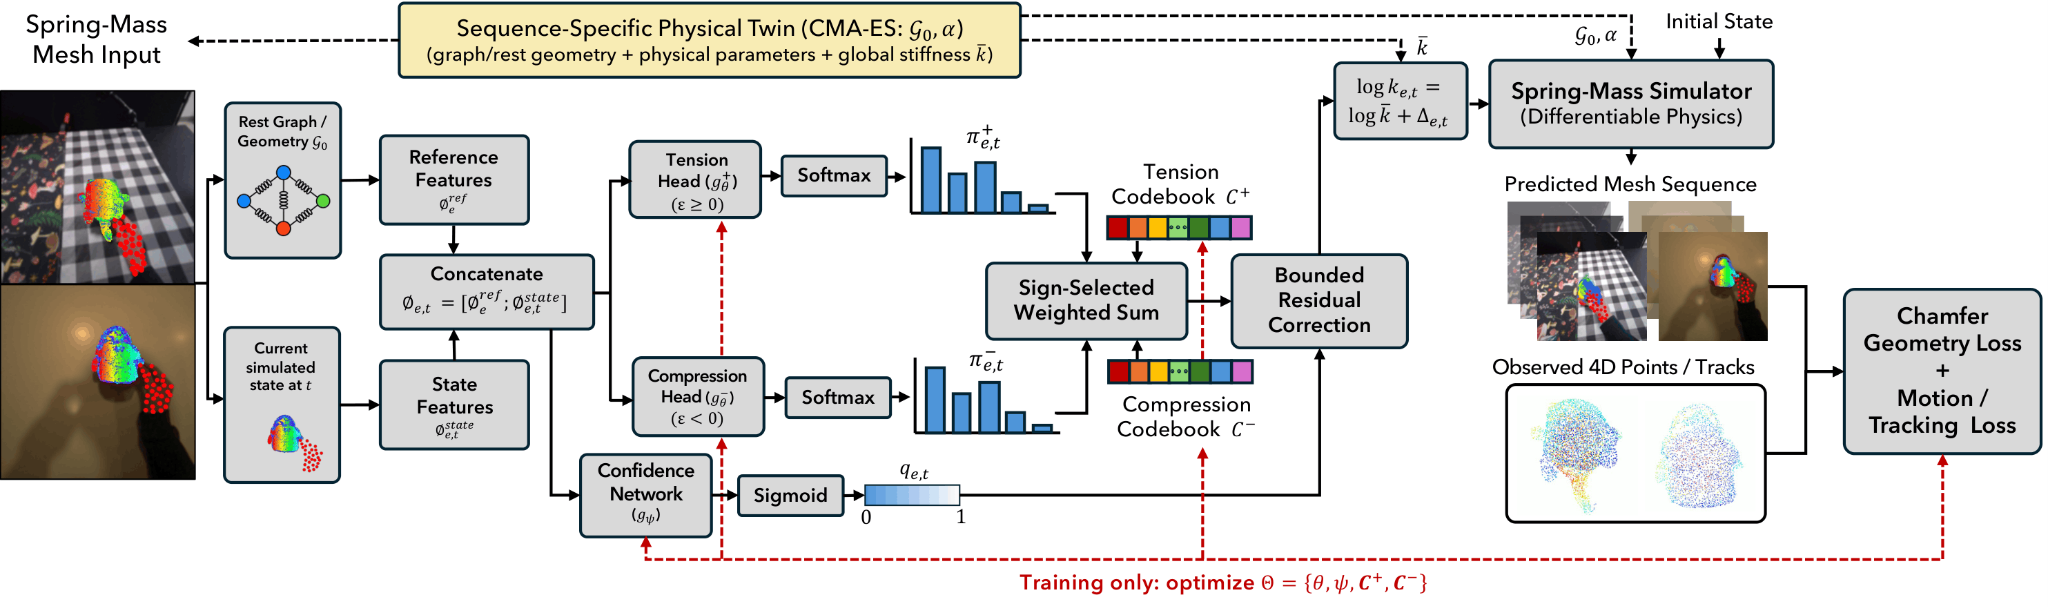
Given a single egocentric RGB video, EgoPhys combines persistent image correspondences with per-frame monocular 3D observations to recover object and manipulator motion. It then fits a sequence-specific spring-mass model with CMA-ES, using geometry, tracked motion, and temporal-smoothness losses together with egocentric adaptations for uncertain contact, support height, and thin objects. Starting from the identified global stiffness, a frozen state-conditioned residual model uses tension and compression codebooks plus a confidence gate to predict bounded local corrections, avoiding dense per-spring test-time optimization.
Experiments
Using identical egocentric observations and a 70/30 temporal split, EgoPhys is compared with adapted PhysTwin and Spring-Gaus baselines. Its sequence-specific twin achieves better resimulation and held-out future prediction, reaching 0.028 Chamfer distance and 0.052 tracking error on future frames before shared residual refinement.
Shared Residual Refinement
Across 11 held-out interactions—four new actions on seen instances and seven unseen instances—the frozen residual improves independently identified sequence-specific twins without dense per-spring test-time optimization. It reduces aggregate future CD from 0.0364 to 0.0319 and TE from 0.0696 to 0.0621, with gains also holding on the unseen towel subset.
Planning & Physical Execution
EgoPhys and adapted PhysTwin serve as forward models for MPPI planning on 11 held-out interactions. Under the same frozen evaluator, EgoPhys lowers geometry and tracking error and raises planning success from 36.4% to 42.4%. Representative trajectories are transferred open-loop to an XArm6 and UR3e without re-identifying the physical model.
Dataset
We collect 19 egocentric deformable-object interactions with a Meta Project Aria Gen 1 wearable camera. Each contains 210 RGB frames (about seven seconds), totaling 3,990 frames. Every interaction follows a chronological 147/63 observed-future split: future frames support checkpoint selection for eight training interactions and evaluation for eleven held-out interactions.
@article{kim2026egophys,
title={EgoPhys: Learning Generalizable Physics Models of Deformable Objects from Egocentric Video},
author={Kim, Hyunjin and Qiu, Ri-Zhao and Jiang, Guangqi and Wang, Xiaolong},
journal={arXiv preprint arXiv:2606.16202},
year={2026}
}